Tools we built along the way
EMPI Engine + Workbench Patient Identity, Resolved Where PHI Already Lives.
For data teams who need one person_id they can explain to governance.
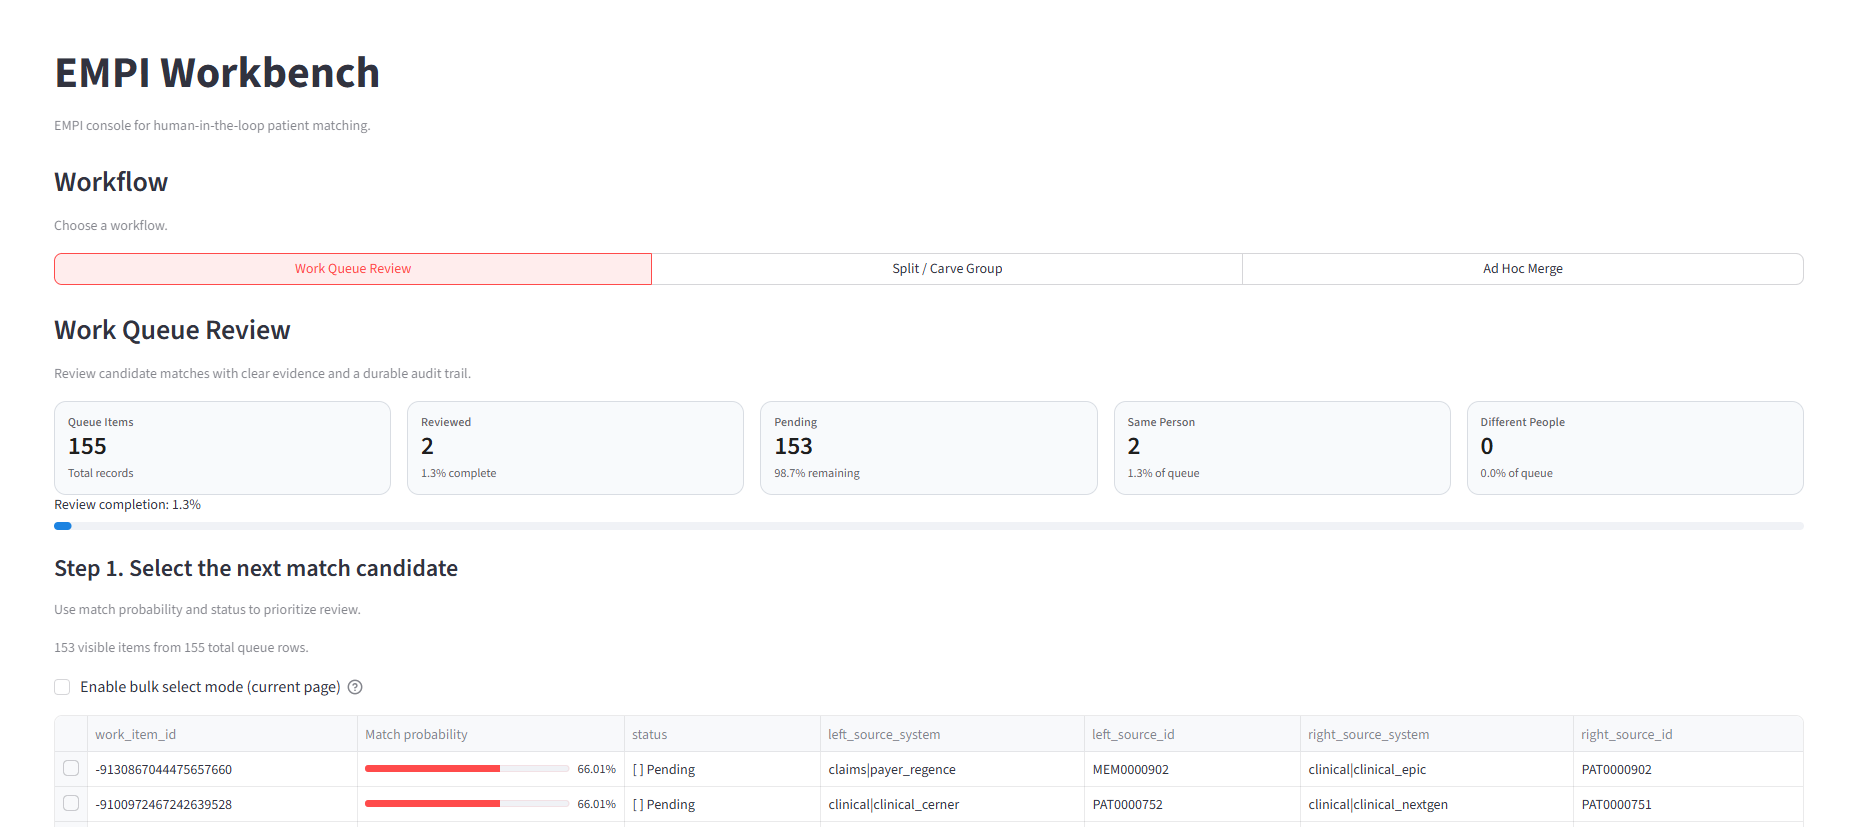
A matching engine, a configuration editor, and a review workbench that run inside your warehouse. Rules are open, stewards work a real queue, and every golden record traces back to the rule or analyst decision that made it.
- Runs on
- Snowflake, Databricks, or Microsoft Fabric
- Delivered as
- A dbt package plus native Streamlit apps
- PHI
- Never leaves your warehouse
- In production
- At a large health system covering about 500,000 lives
From Scattered Records To One Person You Can Explain.
Every run follows the same five steps, and decisions your stewards make carry into the next run.
-
Standardize
Patient and member records from claims and clinical sources are brought into one consistent shape.
-
Score
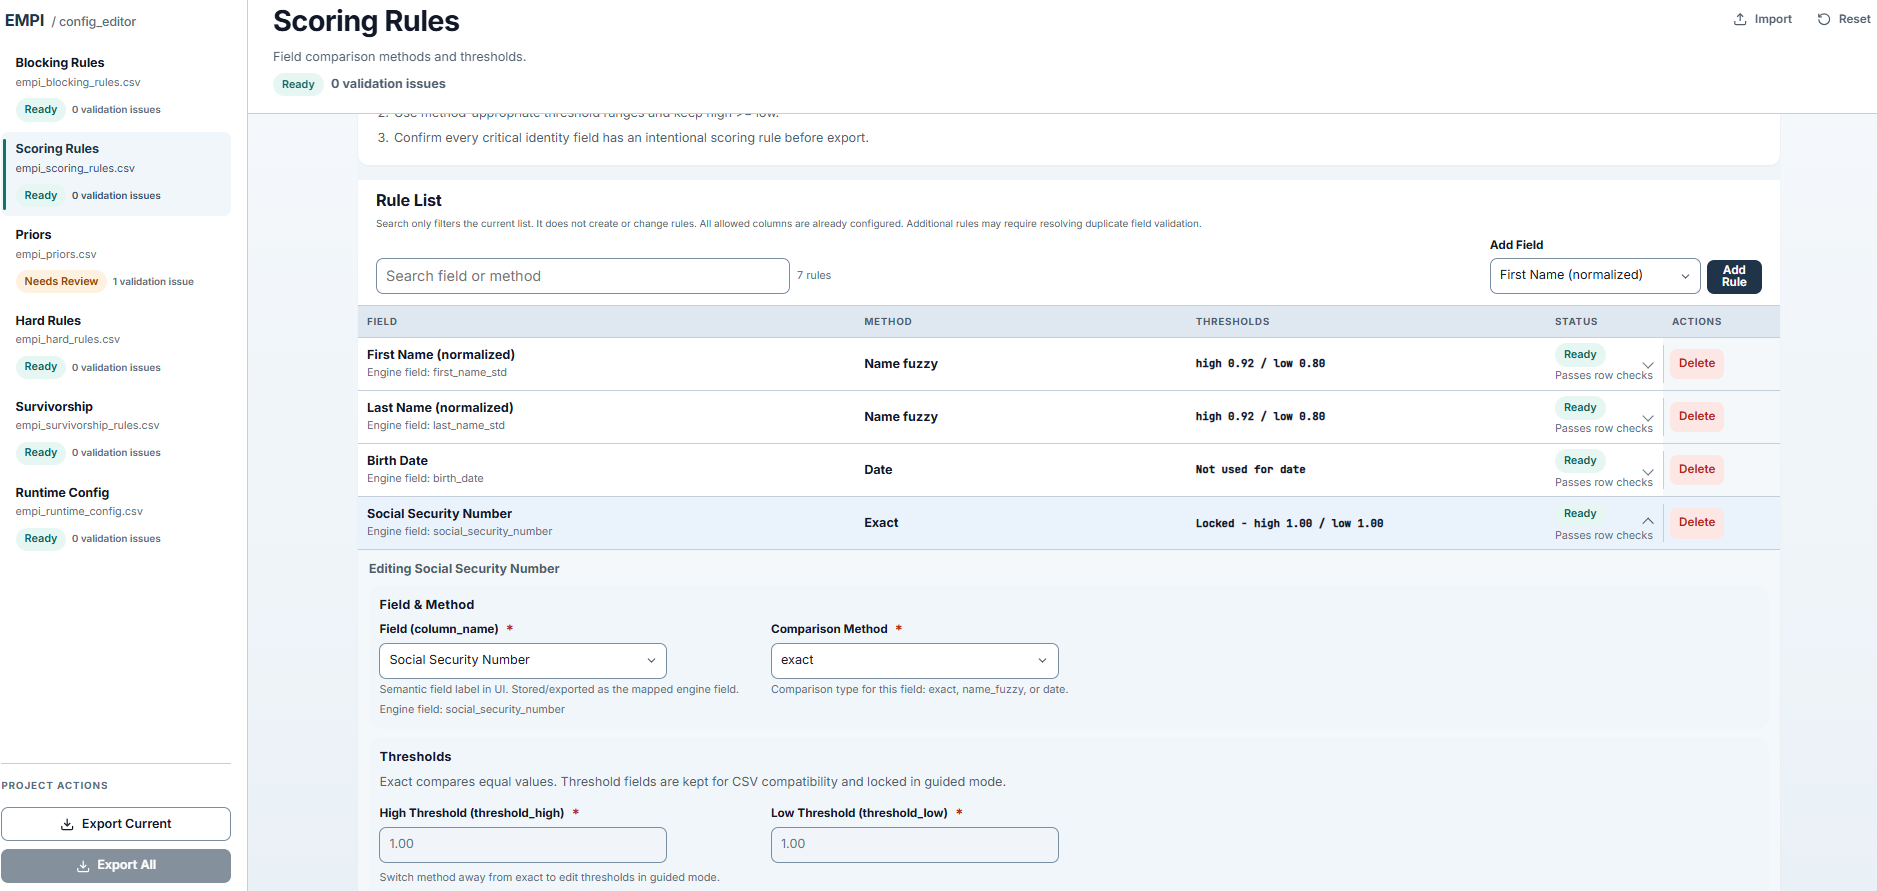
Every plausible pair of records gets a match probability, using rules your team can read and tune.
-
Group
Confident matches become one person. Uncertain ones go to a steward instead of being guessed.
-
Review
Stewards confirm, split, or merge in the workbench. Every decision is audited and remembered.
-
Publish
One stable person ID across your data, a golden record, and claims and clinical tables linked to it.
What Lands In Your Warehouse.
Every output is an ordinary table in your warehouse. Same configuration and same input always produce the same person_id, so dashboards and downstream models do not break between runs.
empi
dbt package, in your warehouse
- empi/ identity, review, audit
- person_crosswalk one ID across every source
- golden_record best value for each field
- provenance where each value came from
- review_queue uncertain pairs for stewards
- decisions every steward call, kept
- claims + clinical/ your tables, linked
Every match has a reason you can query.
Your warehouse, your access controls
Buy The Code Once. Updates If You Want Them.
You buy the code, and it runs in your warehouse under your access controls. Keep it as it is, change it, or subscribe to updates as we improve it.
Nothing is priced per member per month, so the cost does not climb as your population or data volume grows. Compute runs on the warehouse you already pay for.
- Built by
- Healthcare analysts who hit these problems on client work, and built the tool to stop solving them by hand.
- Implemented with
- Your team, on your data, with documentation your team can run without us.
- Maintained by
- Your team, since it is your code. An update subscription keeps it current with ours.
Requirements
- Warehouse
- Snowflake, Databricks, or Microsoft Fabric
- Pipeline
- dbt
- Apps
- Config editor and review workbench on your platform's native app hosting
- Inputs
- Patient and member demographics from claims and clinical sources
Questions Buyers Ask
How is this different from a SaaS EMPI?
A SaaS EMPI needs your PHI in its cloud and usually charges by record or member, so the bill grows with you. This runs in your warehouse, under your IAM, and every rule and threshold is readable rather than inside a black box.
Does any PHI leave our environment?
No. Matching runs in your warehouse, and the apps run on your warehouse platform's own app hosting under your existing access controls. There is no external service.
Do we need to be on Tuva?
It fits Tuva projects directly: it reads the same data model and links the same tables. If your data is not in that shape yet, mapping it is part of the implementation.
What does it cost over time?
You buy the code once. Updates are an optional subscription. Nothing scales with member count or data volume, and the compute runs on your existing warehouse.
Who maintains it after go-live?
Your team can: it is dbt code in your repositories, documented as part of the implementation. If you subscribe to updates, you get our improvements as they ship, and we can support your team directly.
Other tools we built along the way:
Each one follows the same method we use on every engagement.
See EMPI Against Your Own Source Data.
Thirty minutes with Tom or Brad. Bring your sources and where identity breaks today. We will walk through the workbench and what a first run in your warehouse would take.