Tools we built along the way
Predictive Models Predictions Trained On The Population You Score.
For teams whose off-the-shelf risk scores do not fit the data they actually have.
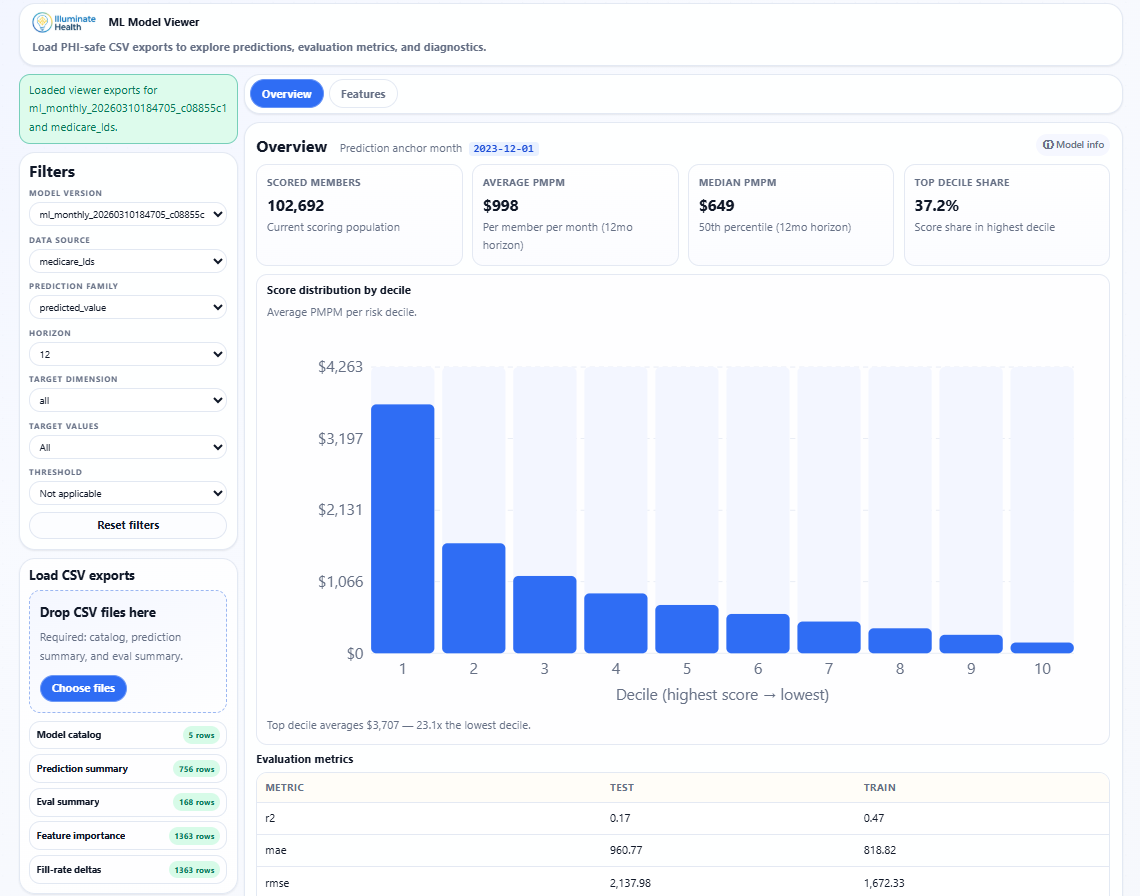
Spend and utilization models that train and score inside your warehouse, on your own claims history, so they learn your payer mix, coding patterns, and cost structure instead of someone else's benchmark cohort.
- Runs on
- Snowflake, Databricks, or Microsoft Fabric
- Delivered as
- A dbt package plus a model viewer
- Predicts
- Spend, inpatient, ED, and SNF use, or targets you define
- In production
- At a large health system covering about 500,000 lives
From Target Policy To Scores You Can Defend.
Training and scoring run in the same dbt pipeline as the rest of your models, so lineage, scheduling, and deployment stay familiar.
-
Define the target
Who is scored, which outcome matters, and over what horizon. Decided with your team and versioned with the code.
-
Learn from your history
Member history from your own data model: utilization, cost, and conditions, as they really appear in your data.
-
Train
Models train inside your warehouse and are versioned, so retraining is a decision, not an accident.
-
Score
Predictions and probabilities land as ordinary tables next to the rest of your data.
-
Check before acting
Accuracy and drift checks to review before predictions reach care management or finance.
What Lands In Your Warehouse.
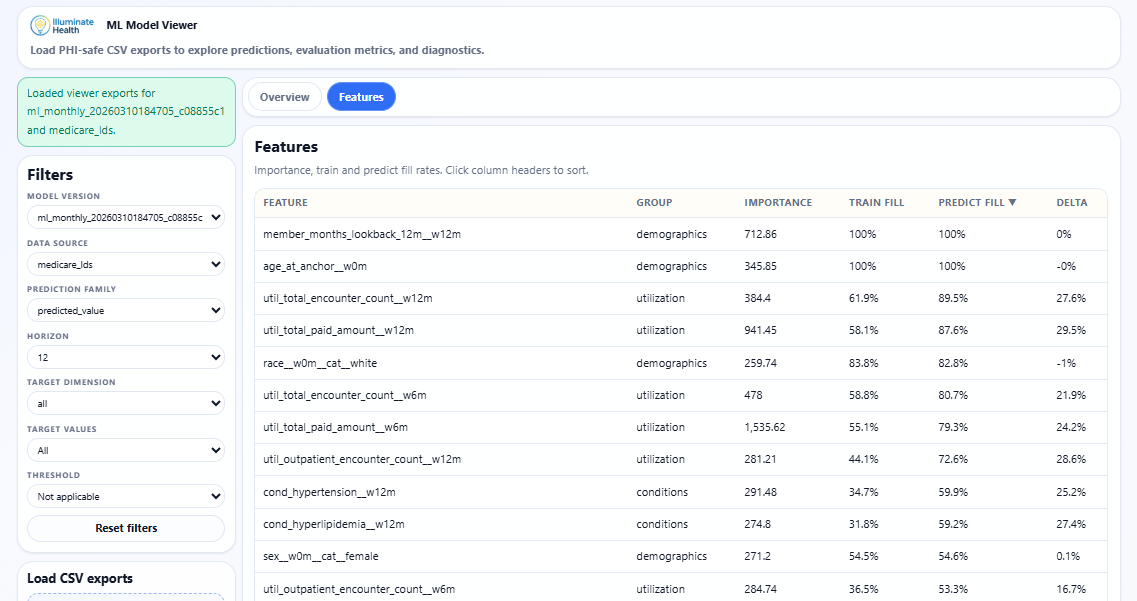
Predictions, probabilities, and accuracy results are ordinary tables next to your data model. Query them, join them to your marts, or feed them to the tools your team already uses.
ml core
dbt package, in your warehouse
- ml/ train, score, evaluate
- predictions by member and horizon
- probabilities chance of an event
- evaluation accuracy, by model version
- model_versions what was trained, and when
- claims + eligibility/ your data model, read only
Every prediction is a row you can query.
No separate ML platform to run
Buy The Code Once. Updates If You Want Them.
You buy the code, and it runs in your warehouse under your access controls. Keep it as it is, change it, or subscribe to updates as we improve it.
Nothing is priced per member per month, so the cost does not climb as your population or data volume grows. Compute runs on the warehouse you already pay for.
- Built by
- Healthcare analysts who hit these problems on client work, and built the tool to stop solving them by hand.
- Implemented with
- Your team, on your data, with documentation your team can run without us.
- Maintained by
- Your team, since it is your code. An update subscription keeps it current with ours.
Requirements
- Warehouse
- Snowflake, Databricks, or Microsoft Fabric
- Pipeline
- dbt
- Inputs
- Claims and eligibility history in a Tuva data model
- Viewer
- Reads PHI-safe summary exports; no member-level data leaves
Questions Buyers Ask
Why not license a commercial risk score?
Benchmark models are built on someone else's population and coding. Even the best explain a small share of individual cost variation on the data they were built for, and less on yours. Training on your own history removes that mismatch.
Do we need a data science platform?
No. Training and inference run in your warehouse as part of dbt. There is no separate ML platform, feature store, or serving layer to stand up.
Can we change what it predicts?
Yes. Targets, horizons, and thresholds are configuration, not code, and we set them with your team during implementation.
What does it cost over time?
You buy the code once. Updates are an optional subscription. Nothing scales with member count or data volume, and the compute runs on your existing warehouse.
Who maintains it after go-live?
Your team can: it is dbt code in your repositories, documented as part of the implementation. If you subscribe to updates, you get our improvements as they ship, and we can support your team directly.
Other tools we built along the way:
Each one follows the same method we use on every engagement.
Bring The Decision You Need To Predict.
Thirty minutes with Tom or Brad. Tell us who you would score and what you would do with the result. We will sketch the target policy and what your history can support.